Vue lecture

Il y a de nouveaux articles disponibles, cliquez pour rafraîchir la page.
🔲 ☆

UCP needs VRM

In Microsoft Advertising’s Agentic Playbook, Laurie Sullivan of MediaPost looks into Microsoft’s “agentic commerce blueprint to guide businesses, retailers, and developers when AI agents make purchases on behalf of humans.”

Meaning agents are out there shopping for customers already. Intentcasting anyone?

Laurie explains,

Microsoft’s “Agentic Playbook” focuses on three priorities:

  • Getting discovered by the agent (which many brands struggle with today).
  • Ensuring the purchase becomes seamless.
  • Having the tools to optimize performance of the intended purchase.

Part of the blueprint details a path for marketers to build a 90-day structure for agentic.

Microsoft’s agentic, that is. She goes on:

One Microsoft product marketing director on the call focusing on product feeds said she can already see a major change in consumer behavior — the way people shop….

Microsoft Copilot runs on the same Universal Commerce Protocol (UCP) that many of its larger partners run on, the company said.

The framework connects Copilot with retail, including giants like Target, Ulta Beauty, and Stripe.

UCP founding partners include Google and Shopify.

UCP is new to me. Wikipedia too. But it does have a website: UCP.dev. There it says, “Universal Commerce Protocol (is) the common language for platforms, agents, and businesses (and) provides building blocks for agentic commerce across industries—from discovery to checkout and beyond—allowing the ecosystem to operate through one standard, without custom builds.”

The page goes on to say UCP is “co-developed by industry leaders,” and “built by the industry, to enable seamless agentic experiences. It solves fragmented user journeys that lead to frustrated users and conversion drop off.”

Solves for the seller, that is. Not for the buyer. Yet.

In Under the Hood: Universal Commerce Protocol (UCP), Amit Handa, Google’s Director of Engineering, Google Commerce, and  Ashish Gupta,  VP/GM Merchant Shopping and Engineering Fellow at Google, write,

By establishing a common language and functional primitives, UCP enables seamless commerce journeys between consumer surfaces, businesses, and payment providers. It is built to work with existing retail infrastructure, and is compatible with Agent Payments Protocol (AP2) to provide secure agentic payments support. It also provides businesses flexible ways to integrate via APIs, Agent2Agent (A2A), and the Model Context Protocol (MCP).

UCP is developed by Google in collaboration with industry leaders including Shopify, Etsy, Wayfair, Target, and Walmart endorsed by over 20 global partners across the ecosystem like Adyen, American Express, Best Buy, Flipkart, Macy’s Inc, Mastercard, Stripe, The Home Depot, Visa, Zalando and many more.

Then,

UCP is built to benefit the entire commerce ecosystem

  • For businesses: UCP empowers you to showcase your unique product and service offerings at shopping touchpoints across consumer interfaces such as AI Mode in Google Search and Gemini app, and others in the future. With UCP, you own your business logic, and you remain the Merchant of Record. UCP is built for retailer flexibility, and provides an ’embedded option’ that allows you to maintain a fully customized checkout experience from day one.

  • For AI platforms: With UCP, you can enable agentic shopping for your audiences. You can simplify business onboarding using standardized APIs while giving them flexibility to use MCP, A2A and existing agent frameworks of their choice.

  • For developers: UCP is an evolving open-source standard designed to be community-driven. We invite you to build the next generation of digital commerce with us.

  • For payment providers: UCP’s open, modular payment handler design enables open interoperability and choice of payment methods. Through this design, UCP enables universal payments that are provable. Every authorization is backed by cryptographic proof of user consent.

  • For consumers: When your favorite brands adopt UCP, it removes friction from product discovery to decision, so you can shop the brands you love, with peace of mind, ensuring you get the best value inclusive of your member benefits.

The last bullet is bullshit, but ignore that. Look at it the consumer side as an empty space where independent customers operate with agents of their own. These agents will roam and engage in the open market. They won’t just be “members” trapped in coercive “loyalty” programs. (Although smart agents can take advantage of whatever privileges might appear in those places too.)

Personal agents are VRM tools. They are the first VRM tools with real power since we started this project two decades ago.

In AI shopping gets simpler with Universal Commerce Protocol updates, Ashish Gupta writes,

Thanks to our partners and community contributors, UCP now provides new optional capabilities including:

  • UCP can help make online shopping more intuitive and convenient, thanks to a new Cart option that will let agents save or add multiple items to a shopping cart at once from a single store — just as a shopper typically would.

  • UCP adopters will be able to access a new Catalog capability that lets agents retrieve select real-time product details from a retailer’s catalog where necessary — like variants, inventory and pricing.

  • Building on existing standards, UCP will also support Identity Linking. That allows shoppers on UCP-integrated platforms to receive the same loyalty or member benefits they would on a retailer’s site when they’re logged in — like pricing or free shipping — making shopping more connected across the web.

Good, but again still just for retailers. Nothing in there addresses a question my wife asked when she first encountered e-commerce in 1995: Why can’t I take my shopping cart from site to site?

Back to Laurie:

On Thursday, Microsoft officially began rolling out “AI Max,” its full suite of features for search advertising campaigns, to all accounts. It optimizes performance across Copilot Search and Bing.

The product provides search term matching that expands reach beyond keyword lists.

It uses keywords, ads, and landing pages, along with intent and contextual signals to find relevant searches campaign might not reach.

It also customizes text by using a campaign’s existing assets and website content to generate and test variations on messages.

The system then selects the most appropriate combinations at auction time.

URL expansion sends people to the page on a brand’s website that best matches their intent.

Instead of always sending traffic to a static landing page, it can route people to the page that best matches what they seek.

With AI Max features turned on, advertisers importing existing search campaigns from Google, for example, will seamlessly carry over into the corresponding Microsoft campaign.

I boldfaced intent because that’s the main force customers bring to the market’s table.

Add intelligence to that. Big AI today has far more market intelligence for customers than it does for companies, because customers are free to roam the whole world’s marketplace, while retailers and their third parties are trapped inside the walls of their own self-interest, offerings, and situations. Also their old mentality: the one that assumes that the best customer is a surveilled and captive one.

We started ProjectVRM twenty years ago next month with a thesis to prove: that free customers are more valuable than captive ones—to themselves and the marketplace. Turns out we couldn’t prove that until AI came along.

AI puts customers at an extreme advantage.  Roger Dunn, Chief Commercial Officer of Thrad, talks about this in a recent  Microsoft Advertising blog post:

When someone asks ChatGPT, Copilot, or Gemini for a product recommendation, the AI assembles a shortlist, usually three to five options, and that shortlist becomes the only consideration set that matters…

The vast majority of consumers still verify AI recommendations before buying. They take that shortlist to Google, to Bing, to a brand website, to YouTube. The verification stage is a confirmation exercise, not an open-ended one. They’re searching for the specific brands the AI mentioned, not starting from scratch…

So trust now operates in two layers.

First, there’s machine trust. From a retailer’s perspective – can an AI agent find you, understand what you sell, and have confidence that your product data is accurate and current? That’s about structured data, reviews, fulfillment reliability, pricing consistency. It’s operational, not emotional.

Second, there’s human trust. When the consumer arrives to verify, does your brand have the credibility, the reputation, the experience to close the deal? That’s the brand equity layer, and it’s not going away.

The brands that win will be the ones who treat product data as a strategic asset while continuing to invest in the emotional signals that make humans want to buy. The mistake is thinking you have to choose.

Product truth comes first signal to matter most, and it’s non-negotiable. AI agents reason over structured attributes: dimensions, compatibility, features, use cases. If those attributes don’t exist as machine-readable data, you’re not even a candidate. In the old world, poor data meant lower conversion. In the agentic world, poor data means you never enter consideration. Consumers aren’t prompting “what’s a good shoe brand.” They’re saying “I’m running a 5K this weekend on mixed terrain and my feet run narrow.” If your catalogue can’t answer that level of specificity, the agent recommends someone who can.

Reviews and third-party signals come second. AI systems synthesise review sentiment to answer highly specific questions. One detailed review explaining how a product performed in a real scenario is worth dozens of generic five-star ratings. Third-party endorsements, expert mentions, and certifications act as trust multipliers that AI increasingly weights.

Fulfillment reliability is third and rising fast. As we move up the automation curve, especially when consumers start authorising agents to purchase within preset rules, delivery reliability becomes a make-or-break signal. If an agent places an order and the delivery fails, the agent learns. Your logistics will become your trust score.

Brand authority is fourth. Still vital, but its mechanism is shifting from emotional halo to verifiable digital identity. Your reputation is increasingly a technical credential that agents use to evaluate trustworthiness.

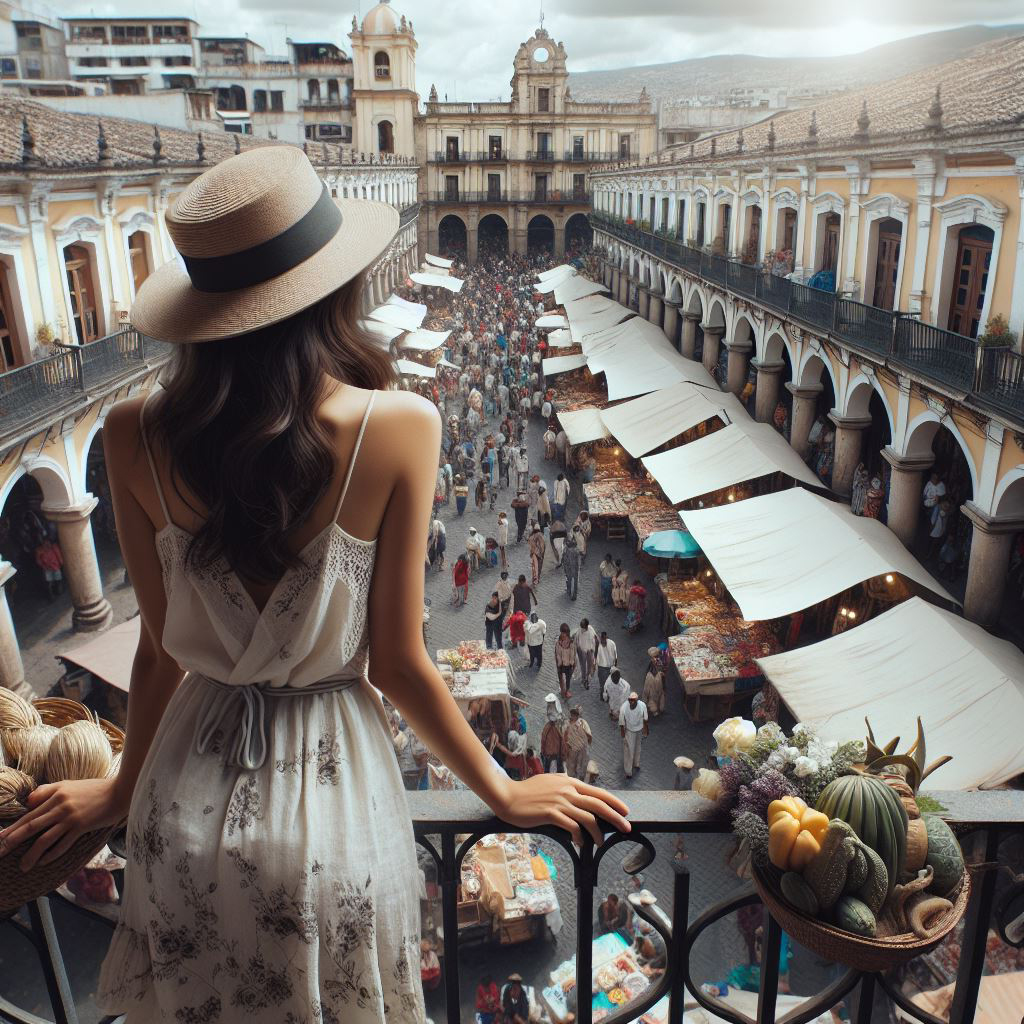
That’s today, when all customers have to work with are Big AI agents. What happens when people get truly personal AIs, in addition to what the giants give them? These will be AIs that give them knowledge and control over the whole corpus of their personal data, meaning everything in this image:

Prompt: A woman uses personal AI to know, get control of, and put to better use all available data about her property, health, finances, contacts, calendar, subscriptions, shopping, travel, and work

What you’re looking at in that image is a far more empowered and agentic customer than one who operates only inside the milieu Roger describes. Because personal AI is by the person, not just for the person. This completely changes the game—especially when the customer comes with her own terms of engagement and  her own identity, credentials, policies, and engagement mechanisms. Both will happen. As Joe Mandese put it in MediaPost last November, Imagine Consumers Delegating Their Relationships With Marketers To Agents.

Nothing in marketing as we’ve known it contemplates the implications of full and independent customer agency, because marketing still lives inside the business-as-usual box to which we addressed The Cluetrain Manifesto twenty-six years ago.  Cluetrain said a lot of stuff to that box, but here was the summary statement:

Chris Locke wrote that. Wish he was still around to see personal AI’s reach break corporate grasp.

From inside that old box, what Microsoft talks about looks like this:

retailer → machine-readable offers → agent → customer

The customer’s side looks like this:

customer → machine-readable intentions/terms/preferences → agent → market → company

The view from above is this:

customer → agent ←  market → agent ← company

Just three things happen in markets:

  • Transactions
  • Conversations
  • Relationships

In the industrial age, which is finally ending, business was focused almost entirely on transactions. Still is, for good reason: without transactions we wouldn’t have markets. It was strong there, but weak in the other two.

Conversations were kept to a minimum because they looked like overhead: costly in time and money. Service was pushed off to call centers, and now call center workers are being replaced by AI robots.

Relationships were about “loyalty” programs in which customers were held captive and milked.

In the agentic world, the opportunities for conversation and relationship are immense—and will drive many more transactions.

Customers and companies can collaborate on countless benefits for each other when imarket ntelligence flows both ways. Products, services, and experiences by customers and companies can all improve together. Guesswork is minimized. So are the operational and moral costs of surveillance.

Lots to work on here.

Bonus linkages:

🔲 ☆

How VRM+CRM Will Play Out

Nitin Badjatia has been laying out more and more reasons, and ways, that enterprises will adapt to customers, rather than the reverse. Read his work and you can start to see what the middle name of both VRM and CRM will mean in the agentic era that is upon us.  His latest three:

From the latest:

The reason the customer contribution matters most is straightforward. The customer is the only body in the relationship that experiences the full arc of it. The organization knows what it built and why. The product knows how it is being used. Only the customer knows what any of it actually means. What they were trying to accomplish, whether they succeeded, and what they wished the enterprise had asked them about before making the decisions it made. All of that is context, and it has never been available to the enterprise on terms either party could trust.

That is about to change. Customer-side agents, operating under a trust protocol like MyTerms, will make the customer’s own account of the relationship available to the enterprise as a first-class contribution to the context layer. MyTerms provides the missing piece the industry has been circling for years. A bilateral agreement, machine-readable and enforceable, that specifies what the customer is willing to share, what the enterprise is allowed to do with it, and what the customer expects in return. With that protocol in place, the customer’s agent will share context the enterprise has never had access to at any point in the history of customer experience.

What the enterprise will receive is not another data feed. It will be a structured account of the relationship from the customer’s own perspective. Why the product was purchased. What problem it was meant to solve. Whether that problem was solved. What has changed in the customer’s circumstances since. What competing options are being considered. What the enterprise could do to strengthen its standing over time. That is a completely different order of information from anything the enterprise’s own instruments have ever produced, because it is the customer’s own account rather than the enterprise’s interpretation of behavior. The customer will have latitude, through a MyTerms contract, in the depth and breadth of the information to share with both the enterprise and the product/service.

The context also compounds in ways the enterprise-side context cannot. The customer’s agent will remember every interaction with every vendor the customer engages with. It will compare experiences across the customer’s full commercial life and surface patterns the customer might never have articulated on their own. When it shares context with the enterprise, it is offering not just what the customer knows about this relationship, but what the agent has learned across many.

But it won’t happen without MyTerms. So let’s build that out.

🔲 ☆

The Original and the Eventual Intention Economy

The Intention Economy subtitle. It’s the whole thing, right there.

A recent post by Simon Taylor on X expresses something important about AI agents and markets: if an AI agent arrives in a market with a clear mandate—

Get me X. Budget Y. Constraints Z.

—it obsolesces business-as-usual for digital marketing.

See, all of martech and adtech starts with the assumption that human intent is fuzzy and manipulable—and that the best customers are captive and manipulated. Let’s look at this from three angles, which are also the three things that happen in markets:

  • transactions
  • conversations
  • relationships.

On the transaction side, companies invest heavily in tracking people, analyzing their behavior, targeting ads at them, and then (in many cases) rationalizing extremely wasteful results. Plus, of course, discounting or ignoring boundless negative externalities, such as the annoying people to new extremes and massively abusing personal privacy. (In fact, the system treats absent personal privacy as a base feature.) Anyway, the entire surveillance-based advertising fecosystem exists to guess what people want, or to influence what they might want.

On the relationship side, all we have so far is on the sell side: CRM, for Customer Relationship Management, and CX, for Customer Experience. We’ve been trying here to build (or to encourage building) systems for VRM, for Vendor Relationship Management, to give CRM customer hands to shake. But, in VRM’s absence, CRM is all we’ve got. One hand clapping. Or slapping. Or pushing prospects into a funnel.

What many of us, including Simon Taylor, suggest is facilitating conversation through AI agents. Simon’s case, specifically, is that an agent representing a person doesn’t need to be guessed at. It already knows the user’s intent. So there is no attention to capture and no desire to manufacture or manipulate. The demand signal is clear from the start. That’s why he says agents can collapse the attention economy.

The underlying shift in this direction has been visible for a long time. In The Intention Economy: When Customers Take Charge (Harvard Business Review Press, 2012), I argued that markets work best when customers drive them with clear signals of demand, rather than when sellers try to infer demand through surveillance and unwelcome persuasion. I also said markets can be far richer and more vital when customers and companies operate as equals, with relationships based on mutual interest rather than forms of coercion (such as “loyalty” programs that aren’t).

The work of Vendor Relationship Management (VRM) has been about correcting that imbalance.

Instead of companies managing relationships with customers through CRM (Customer Relationship Management) systems, we need customers able to manage relationships with vendors through VRM (Vendor Relationship Management) tools.

Note that relationship is the middle name of both CRM and VRM. Markets are not just about transactions. They are about relationships that continue over time.

That’s why a working intention economy will involve far more than simple buying transactions.

As Esteban Kolsky once put it, companies often focus almost entirely on the “buy cycle.” But customers live mostly in the “own cycle”—the long period of using, maintaining, fixing, improving, and learning from the products and services they already have:

In an intention economy, intelligence about that experience flows both ways between customers and companies. I wrote about this recently here:

Market intelligence that flows both ways.

VRM has long described one key mechanism for this: intentcasting, where customers signal their needs directly to the market rather than being targeted by guesses and ads.

Agents may make this far more feasible than it was when we first started talking about VRM nearly two decades ago.

But there’s an important point that often gets missed in current AI discussions.

The agency that matters most is the person’s, not the agent’s.

A personal AI agent is an instrument—like a phone, a computer, or a car. It acts on behalf of the individual, but the intention behind it must be the person’s own.

And that leads to another requirement:

The only truly personal agents will be owned and operated by individuals.

We don’t have that yet.

What we have instead are assistants that live inside corporate systems—helpful, sometimes impressive, but ultimately operating within feudal structures run by very large companies.

They are, at best, friendly suction cups on the tentacles of giants.

Individuals may well rent or borrow AI models from those giants. But the agents that represent us should operate inside our own environments, in our exclusive interest, rather than inside corporate systems whose interests may diverge from ours.

In other words, our agents should live in our own castles, not inside someone else’s kingdom.

When that happens—when individuals can show up in markets through tools they control—then the deeper shift becomes possible: from guesswork based on surveillance of captive customers to servicing self-qualified leads from free customers in the open marketplace.

Markets then begin to work the way markets are supposed to work: with demand and supply meeting in the open, in relationships that can last far beyond a single transaction.

This is also where work like MyTerms and the emerging ecosystem around personal AI becomes important. If individuals are to operate in markets through their own agents, those agents need ways to assert the person’s terms, preferences, and boundaries in forms that other systems can recognize and respect.

That is the direction VRM has been pointing for nearly twenty years: toward a world where individuals can arrive in markets with their own tools, their own data, and their own terms—and where markets can finally listen.

When that happens, markets will stop guessing what customers want—and start hearing them.

[Later… I actually wrote this post about a month ago, and put off publishing it while I worked on other things. Meanwhile, Adrian Gropper posted A Fork in the Road, which is required reading. I thank him for reminding me in the comments below, and for being a founding participant in ProjectVRM—going back to our earliest meetings almost 20 years ago.]

🔲 ☆

Finally Fixing Health Care

Source: ChatGPT

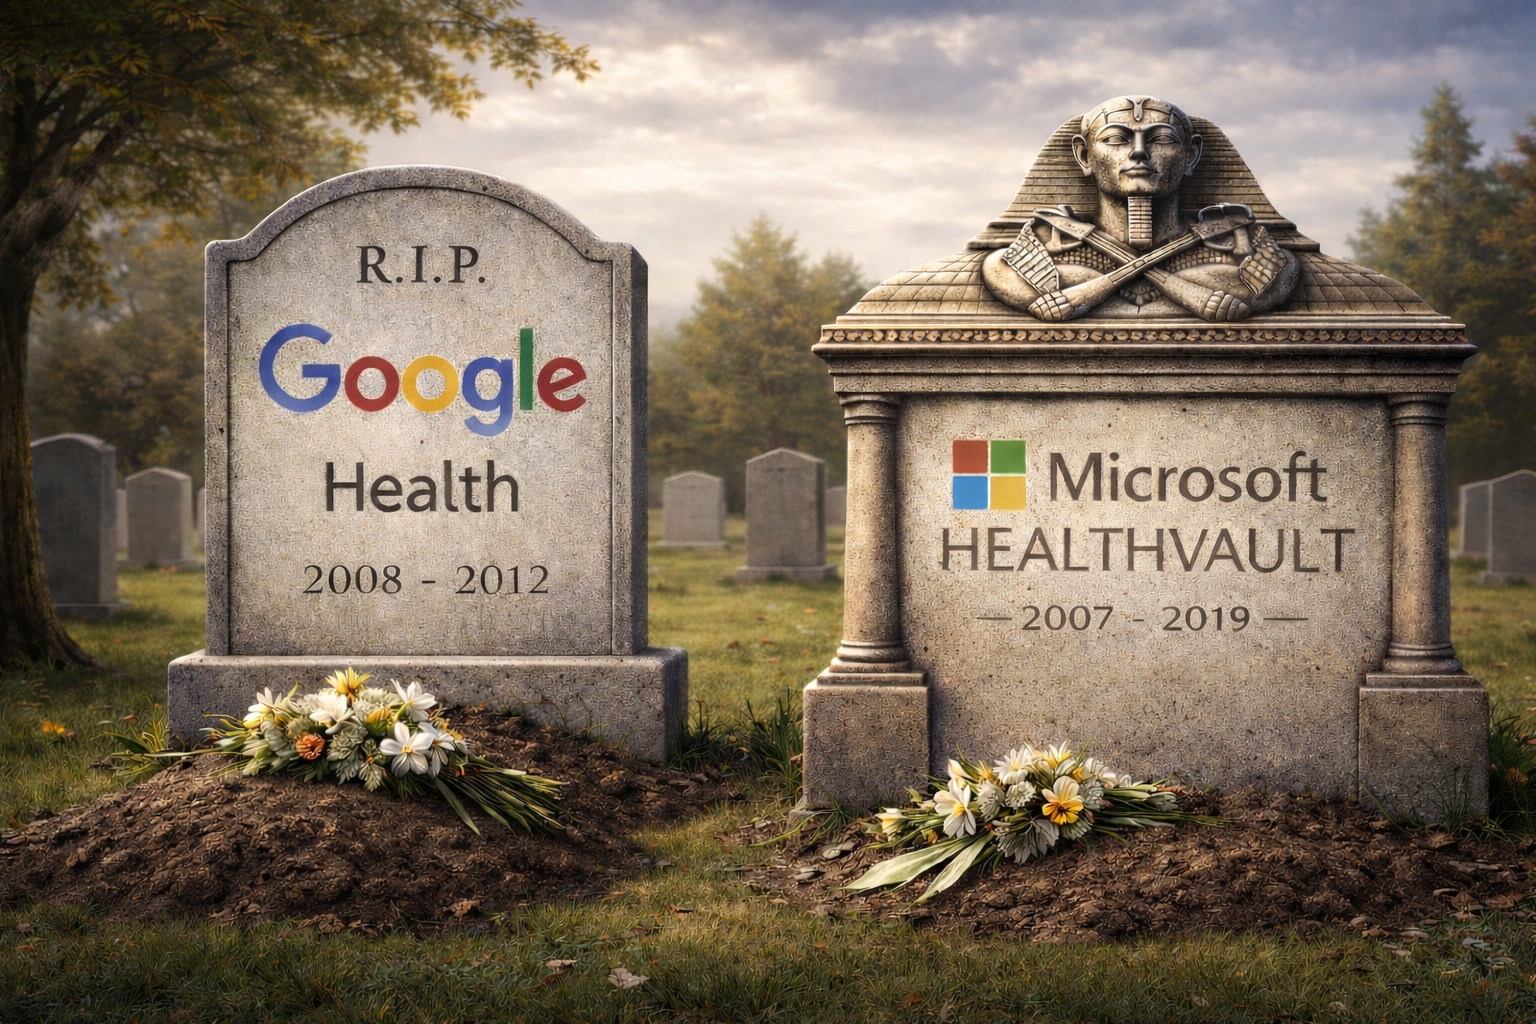
Interesting how old posts get new traffic. The heaviest traffic this morning is to Health Care Relationship Management, which ran almost nineteen years ago. That post concerned a Steve Lohr story in the NY Times titled Google and Microsoft Look to Change Health Care.  The gist:

The Google and Microsoft initiatives would give much more control to individuals, a trend many health experts see as inevitable. “Patients will ultimately be the stewards of their own information,” said John D. Halamka, a doctor and the chief information officer of the Harvard Medical School.

The initiatives were Google Health  and Microsoft Healthvault. Never mind why they died. Those links will tell you. What matters more is what I said way back then: The key, as with all VRM projects, is that the solution needs to be anchored on the customer side — in this case the patient side — of the relationship.

As it happens, Adrian Gropper, techie and MD, was on this case long before Google and Microsoft showed up to waste $billions failing to solve a problem they could only compound. And he’s still at it, with HIE of One and related efforts. Here is his Substack. These subjects will be on the floor at VRM Day and IIW later this month. VRM for healthcare will save the world $billions, in addition to countless lives.

Here’s Adrian’s latest.

🔲 ☆

Shooting for the World

There is no organisation on Earth with a more audacious purpose than this one:

From Customer Commons’ current index page.

This isn’t shooting for the Moon. It’s shooting for the whole world of business.

What Customer Commons wants to restore isn’t just what was lost when the Internet got real. (For example, privacy.) Customer Commons also wants to restore personal agency that was lost when Industry won the Industrial Revolution. That’s when jobs replaced work, labour replaced teams, and customers became consumers.

That last shift, Jerry Michalski explains, was from human beings to “gullets with wallets and eyeballs.” After that shift, freedom of contract in marketplaces was enjoyed only by businesses. Not by gullets.

Customer Commons was created to change that. It was spun out of ProjectVRM as a 501(c)3 nonprofit in 2013, shortly after Harvard Business Review Press published  The Intention Economy: When Customers Take Charge. That book specifically gave Customer Commons the job of doing for personal privacy terms what Creative Commons did for personal copyright.  And to do it by making privacy a contract between customers and businesses, rather than a “consent” to whatever the hell businesses wanted to shove down our gullets. (For example, with interruptive cookie “choices” that really aren’t and leave no audit trail.)

Work on that began in 2017, when the IEEE approached Customer Commons with an offer to host development of a standard for machine-readable personal privacy terms. That standard, officially called IEEE 7012-2025, and nicknamed MyTerms, was published this past January, concluding nine years of work.

Now what?

MyTerms is a great start toward completing Customer Commons’ audacious mission. Here are some goals we will achieve when that mission is accomplished:

  1. VRM will be a business category, welcomed and engaged by CRM and CX functions on the sell sides of markets.
  2. We will have proof that free customers are worth more than captive ones—to companies they engage, to whole markets, and to themselves. This was ProjectVRM’s original mission in 2006.
  3. The intention economy will materialize when voluntary signaling from customers to companies outperforms and obsolesces surveillance as the primary means for companies to obtain data about customers.

MyTerms is required for all three, because a contract is the only way for companies to commit to respecting personal privacy, and MyTerms is the standard for doing that.

So the first challenge is to make Customer Commons viable as the first mover in establishing MyTerms in the world.

The second challenge is to make Customer Commons substantial enough to lead work toward all three of the challenges listed above. Customer Commons won’t be the only entity working on those. In the U.S., Consumer Reports has already stepped forward as a natural ally.  MyData Global is partnering with Customer Commons in standing up the MyTerms Alliance, which is HQ’d in Europe. There are many other potential partners, such as Mozilla and the EFF.

There is development work on MyTerms already. You can learn more about those at VRM Day, IIW, and AIW, which run M-F through the last week of this month (April 27 to May 1) at the Computer History Museum in Silicon Valley.

Here are other ideas that have been floated in the past for Customer Commons:

  1. Customers Union. Being for customers what the AARP is for retired people. Only bigger, because it would include everybody who is a customer of anything. This isn’t far from Consumers Union, which begat Consumer Reports, and is now its advocacy group.
  2. CustomerCon. A trade show with company booths run by customers, to which companies are invited as guests. Key feature: no complaining. Guest companies are treated only to positive and constructive ideas. HT to Tim Hwang for helping come up with that one.
  3. Omie. A tablet with apps free of Google and Apple. HT to Iain Henderson.
  4. The ByWay, a new path for local e-commerce.
  5. The Free Customer Award. This would be given to companies that value free customers and do nothing to entrap them. The canonical example described in The Intention Economy is Trader Joe’s. But there are others. In-N-Out Burger, for example.

I share those only to give you an idea of how big and influential Customer Commons might be, and how it’s possible to have fun making a new and better economy happen.

We’re not at Square One. Customer Commons is an extant nonprofit, has an energetic board, and a huge accomplishment by getting MyTerms finished. What it needs now is to build out a working organisation. How can we do that?

Let’s look at how Creative Commons got rolling in 2002 and kept moving after that. Here is what I’ve found in diggings so far—

  • The History of Creative Commons in Wired (December 2011) says, “An hour after the court’s decision was announced, the William and Flora Hewlett Foundation presented Creative Commons with $1,000,000 to launch the movement.” The case was Eldred v. Ashcroft.
  • In 2008, there was a successful funding challenge from Hewlett: “The 5×5 challenge, issued in honor of Creative Commons’ fifth birthday, called for the organization to find five funders to each promise five years of support at $500,000 per year. In addition to the Hewlett Foundation, Creative Commons received pledges of $500,000 in yearly support for five years from Omidyar Network, as well as from an anonymous European trust. Google has pledged $300,000 in support renewable for five years, while Mozilla and Red Hat have each pledged to contribute $100,000 annually for five years. The final block of support comes from the board of Creative Commons, which has promised to personally raise or contribute $500,000 to the organization annually for five years.”(Source: Creative Commons Newsletter No.5, February 2008)
  • A Creative Commons  announcement in April 2008 said, “We’re thrilled about a major new grant of $4 million from the William and Flora Hewlett Foundation, consisting of $2.5 million to provide general support to Creative Commons over five years, as well as $1.5 million to support ccLearn.”
  • A MacArthur grant search reports a total of $3,225,000 provided between 2002 and 2022:
    • $750,000 in 2005 to support general operations for three years
    • $500,000 in 2007 to support Science Commons for two years
    • $700,000 in2008 to support general operations and an endowment campaign for three years
    • $25,000 in 2015 to provide travel and other support for attendees of the Creative Commons Global Summit in South Korea, for two months. The meeting was also funded in part by the Institute for Museu m and Library Services and th e Gates Foundation, and by the Korean Ministry of Culture, Sports and Tourism ($25,000), Mozilla ($10,000), and the Wikimedia Foundation ($10,000).
    • $50,000 in 2022 to support dedicated programming on open journalism issues at the 2023 Global Summit, “which is an annual event that brings together educators, artists, technologists, legal experts, and activists to promote the power of open licensing and global access.”

So, by inference, the phases were roughly this:

  • Launch (2001–2002) $1M of initial funding
  • Early build-out (2002–2004) +$1–3M with  additional foundation support
  • Continuous operations (2005 onward) at ~$1–3M/year

That gives us an idea of what we need to raise. (Given inflation, multiply those numbers by 1.5x.)

I’ll tell you more when I find out more. Meanwhile, watch this space. Better yet, jump in and help out.


🔲 ☆

Without Privacy, VRM Can’t Happen

Nor can CRM. Not really. The middle name of both is Relationship, and those require respect for each other’s boundaries. We don’t have that yet online, and can’t without working standards (hello MyTerms), tech, and norms. In fact, the opposite prevails: extreme exploitation of absent personal privacy.

Helen Nissenbaum has been teaching us that for decades, and working on solutions. One is Adnauseum, which may be on your browser already.  It works (says that last link) “by automating ad clicks universally and blindly on behalf of its users. Built atop uBlock Origin, AdNauseam quietly clicks on every blocked ad, registering a visit on ad networks’ databases. As the collected data gathered shows an omnivorous click-stream, user tracking, targeting and surveillance become futile.” In another word, obfuscation.

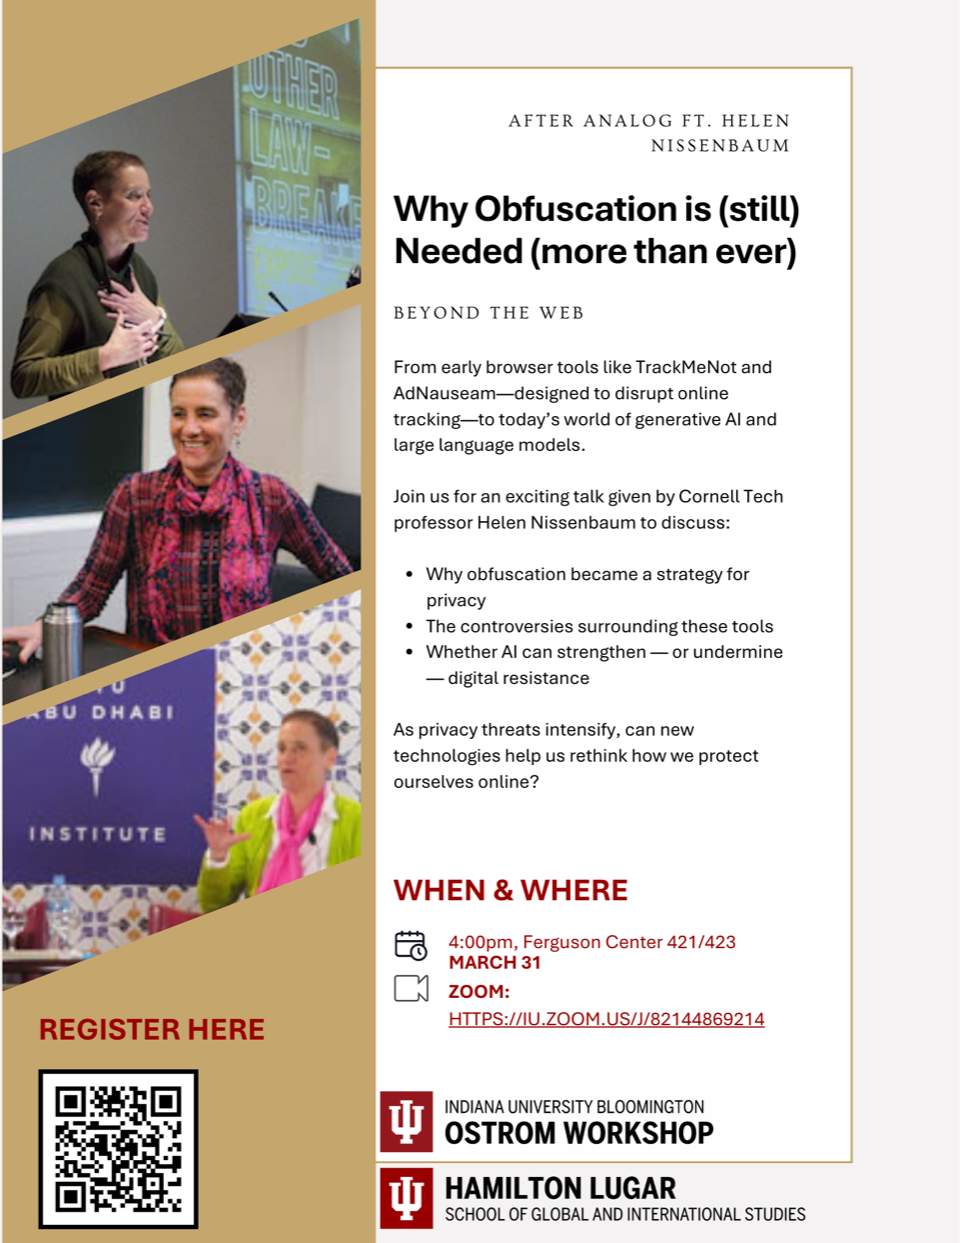
And that’s what Helen will unpack when she speaks in our salon series here at Indiana University next Tuesday at 4 pm Eastern, and on Zoom. Her title is Why Obfuscation is (still) Needed (more than ever). Here’s the flyer, with the registration and Zoom links:

And in case you don’t click on that, here it is again.

See you there.

🔲 ☆

On Customer Constituency

A customer looks at a market where choice rules and nobody owns anybody. Source: Microsoft Copilot | Designer

I’m in a discussion of business constituencies. On the list (sourced from the writings of Doug Shapiro) are investors, employees, suppliers, customers, and regulators.

The first three are aware of their membership, but the last two? Not so sure.

Since ProjectVRM works for customers, let’s spin the question around. Do customers have a business constituency? If so, businesses are members by the customer’s grace. She can favor, ignore, or more deeply engage with any of those businesses at her pleasure. She does not “belong” to any of them, even though any or all of them may refer to her, or their many other customers, with possessive pronouns.

Take membership (e.g. Costco, Sam’s Club) and loyalty (CVS, Kroger) programs off the table. Membership systems are private markets, and loyalty programs are misnomered. (For more about that, read the “Dysloyalty” chapter of The Intention Economy.)

Let’s look instead at businesses that customers engage as a matter of course: contractors, medical doctors, auto mechanics, retail stores, restaurants, clubs, farmers’ markets, whatever. Some may be on speed dial, but most are not. What matters in all cases is that these businesses are responsible to their customers. “The real and effectual discipline which is exercised over a workman is that of his customers,” Adam Smith writes. “It is the fear of losing their employment which restrains his frauds and corrects his negligence.” That’s what it means to be a customer’s constituent.

An early promise of the Internet was supporting that “effectual discipline.” For the most part, that hasn’t happened. The “one clue” in The Cluetrain Manifesto said “we are not seats or eyeballs or end users or consumers. we are human beings and our reach exceeds your grasp. deal with it.” Thanks to ubiquitous surveillance and capture by corporate giants and unavoidable platforms, corporate grasp far outreaches customer agency.

That’s one reason ProjectVRM has been working against corporate grasp since 2006, and just as long for customer reach. Our case from the start has been that customer independence and agency are good for business. We just need to prove it.

☑️ ☆

ProjectVRM 2.0

It took a while, but our website is now on its own. Big thanks go to the Berkman Klein Center for hosting us on its blog server since 2006. Also for continuing to host our mailing list and our wiki. And to all the friends who helped, including those at WordPress and Pressable, who made the transition smooth and complete. Links to every post and page we’ve published at blogs.harvard.edu/vrm/ (our old location) now travel down the same directory paths at projectvrm.org/. There will be no 404s. This is a rare thing for any site that moves from one host to another.

Clearly, this is not the one-year project we imagined in the first place. It may not be a one-generation project. But we will get from the state on the left above to the one on the right. And thanks to Gapingvoid‘s Hugh MacLeod for drawing that illustration in the first place, way back in 2005.


☑️ ☆

Toward a lexicon for advertising in both directions

We need a lexicon for the different ways buyers and sellers express their intentions to each other. Or, one might say, advertise.

On the demand side (⊂) we have what in ProjectVRM we’ve called intentcasting and (earlier) personal RFP. Scott Adams calls it broadcast shopping and John Hagel and David Siegel both (in books by that title) call it pull.

On the sell side (⊃) I can list at least six kinds of advertising alone that desperately need distinctive labels. To pull them apart, these are:

  1. Brand advertising. This kind is aimed at populations. All of it is contextual, meaning placed in media, TV or radio programs, or publications, that appeal broadly or narrowly to a categorized audience. None of it is tracking-based, and none of it is personal. Little of it wants a direct response. It simply means to impress. This is also the form of advertising that burned every brand you can name into your brain. In fact the word brand itself was borrowed from the cattle industry by Procter & Gamble in the 1930s, when it also funded the golden age of radio. Today it is also what sponsors all of sports broadcasting and pays most sports stars their massive salaries.
  2. Search advertising. This is what shows up with search results. There are two very different kinds here:
    1. Context-based. Not based on tracking. This is what DuckDuckGo does.
    2. Context+tracking based. This is what Google and Bing do.
  3. Tracking-based advertising. I’ve called this adtech. Cory Doctorow calls it ad-tech. Others call it ad tech. Some euphemize it as behavioralrelevant, interest-based, or personalized. Shoshana Zuboff says all of them are based on surveillance, which they are. So many critics speak of it as surveillance-based advertising.
  4. Advertising that’s both contextual and personal—but only in the sense that a highly characterized individual falls within a group, or a collection of overlapping groups, chosen by the advertiser. These are Facebook’s Core, Custom and Look-Alike audiences. Talk to Facebook and they’ll tell you these ads are not meant to be personal, though you should not be surprised to see ads for shoes when you have made clear to Facebook’s trackers (on the site, the apps, and wherever the company’s tentacles reach) that you might be in the market for shoes. Still, since Facebook characterizes every face in its audience in almost countless ways, it’s easy to call this form of advertising tracking-based.
  5. Interactive advertising. Vaguely defined by Wikipedia here,  and sometimes called conversational advertising,  the purpose is to get an interactive response from people. The expression is not much used today, even though the Interactive Advertising Bureau (IAB) is the leading trade association in the tracking-based advertising field and its primary proponent.
  6. Native advertising, also called sponsored content, is advertising made to look like ordinary editorial material.

The list is actually much longer. But the distinction that matters is between advertising that is tracking-based and the advertising that is not. As I put it in Brands need to fire adtech,

Let’s be clear about all the differences between adtech and real advertising. It’s adtech that spies on people and violates their privacy. It’s adtech that’s full of fraud and a vector for malware. It’s adtech that incentivizes publications to prioritize “content generation” over journalism. It’s adtech that gives fake news a business model, because fake news is easier to produce than the real kind, and adtech will pay anybody a bounty for hauling in eyeballs.

Real advertising doesn’t do any of those things, because it’s not personal. It is aimed at populations selected by the media they choose to watch, listen to or read. To reach those people with real ads, you buy space or time on those media. You sponsor those media because those media also have brand value.

With real advertising, you have brands supporting brands.

Brands can’t sponsor media through adtech because adtech isn’t built for that. On the contrary, adtech is built to undermine the brand value of all the media it uses, because it cares about eyeballs more than media.

Adtech is magic in this literal sense: it’s all about misdirection. You think you’re getting one thing while you’re really getting another. It’s why brands think they’re placing ads in media, while the systems they hire chase eyeballs. Since adtech systems are automated and biased toward finding the cheapest ways to hit sought-after eyeballs with ads, some ads show up on unsavory sites. And, let’s face it, even good eyeballs go to bad places.

This is why the media, the UK government, the brands, and even Google are all shocked. They all think adtech is advertising. Which makes sense: it looks like advertising and gets called advertising. But it is profoundly different in almost every other respect. I explain those differences in Separating Advertising’s Wheat and Chaff:

…advertising today is also digital. That fact makes advertising much more data-driven, tracking-based and personal. Nearly all the buzz and science in advertising today flies around the data-driven, tracking-based stuff generally called adtech. This form of digital advertising has turned into a massive industry, driven by an assumption that the best advertising is also the most targeted, the most real-time, the most data-driven, the most personal — and that old-fashioned brand advertising is hopelessly retro.

In terms of actual value to the marketplace, however, the old-fashioned stuff is wheat and the new-fashioned stuff is chaff. In fact, the chaff was only grafted on recently.

See, adtech did not spring from the loins of Madison Avenue. Instead its direct ancestor is what’s called direct response marketing. Before that, it was called direct mail, or junk mail. In metrics, methods and manners, it is little different from its closest relative, spam.

Direct response marketing has always wanted to get personal, has always been data-driven, has never attracted the creative talent for which Madison Avenue has been rightly famous. Look up best ads of all time and you’ll find nothing but wheat. No direct response or adtech postings, mailings or ad placements on phones or websites.

Yes, brand advertising has always been data-driven too, but the data that mattered was how many people were exposed to an ad, not how many clicked on one — or whether you, personally, did anything.

And yes, a lot of brand advertising is annoying. But at least we know it pays for the TV programs we watch and the publications we read. Wheat-producing advertisers are called “sponsors” for a reason.

So how did direct response marketing get to be called advertising ? By looking the same. Online it’s hard to tell the difference between a wheat ad and a chaff one.

Remember the movie “Invasion of the Body Snatchers?” (Or the remake by the same name?) Same thing here. Madison Avenue fell asleep, direct response marketing ate its brain, and it woke up as an alien replica of itself.

This whole problem wouldn’t exist if the alien replica wasn’t chasing spied-on eyeballs, and if advertisers still sponsored desirable media the old-fashioned way.

Bonus link.

I wrote that in 2017. The GDPR became enforceable in 2018 and the CCPA in 2020.  Today more laws and regulations are being instituted to fight tracking-based advertising, yet the whole advertising industry remains drunk on digital, deeply corrupt and delusional, and growing like a Stage IV cancer.

We live digital lives now, and most of the advertising we see and hear is on or through glowing digital rectangles. Most of those are personal as well. So, naturally, most advertising on those media is personal—or wishes it was. Regulations that require “consent” for the tracking that personalization requires do not make the practice less hostile to personal privacy. They just make the whole mess easier to rationalize.

So I’m trying to do two things here.

One is to make clearer the distinctions between real advertising and direct marketing.

The other is to suggest that better signaling from demand to supply, starting with intentcasting, may serve as chemo for the cancer that adtech has become. It will do that by simply making clear to sellers what buyers actually want and don’t want.


🔲 ⭐

The Rise of Robot Retail

end of personal dealings
From Here Comes the Full Amazonification of Whole Foods, by Cecelia Kang (@CeceliaKang) in The New York Times:

…In less than a minute, I scanned both hands on a kiosk and linked them to my Amazon account. Then I hovered my right palm over the turnstile reader to enter the nation’s most technologically sophisticated grocery store…

Amazon designed my local grocer to be almost completely run by tracking and robotic tools for the first time.

The technology, known as Just Walk Out, consists of hundreds of cameras with a god’s-eye view of customers. Sensors are placed under each apple, carton of oatmeal and boule of multigrain bread. Behind the scenes, deep-learning software analyzes the shopping activity to detect patterns and increase the accuracy of its charges.

The technology is comparable to what’s in driverless cars. It identifies when we lift a product from a shelf, freezer or produce bin; automatically itemizes the goods; and charges us when we leave the store. Anyone with an Amazon account, not just Prime members, can shop this way and skip a cash register since the bill shows up in our Amazon account.

And this is just Amazon. Soon it will be every major vendor of everything, most likely with Amazon as the alpha sphincter among all the chokepoints controlled by robotic intermediaries between first sources and final customers—with all of them customizing your choices, your prices, and whatever else it takes to engineer demand in the marketplace—algorithmically, robotically, and most of all, personally.

Some of us will like it, because it’ll be smooth, easy and relatively cheap. It will also subordinate us utterly to machines. Or perhaps udderly, because we will be calves raised to suckle on the teats of retail’s robot cows.

This system can’t be fixed from within. Nor can it be fixed by regulation, though some of that might help. It can only be obsolesced by customers who bring more to the market’s table than cash, credit, appetites and acquiescence to systematic training.

What more?

Start with information. What do we actually want (including, crucially, to not be bothered by hype or manipulated by surveillance systems)?

Add intelligence. What do we know about products, markets, needs, and how things actually work than roboticized systems can begin to guess at?

Then add values, such as freedom, choice, agency, care for others, and the ability to collectivize in constructive and helpful ways on our own.

Then add tech. But this has to be our tech: customertech that we bring to market as independent, sovereign and capable human beings. Not just as “users” of others’ systems, or consumers (which Jerry Michalski calls “gullets with wallets and eyeballs”) of whatever producers want to feed us.

Time for solutions. Here is a list of fourteen market problems that can only be solved from the customers’ side.

And yes, we do need help from the sellers’ side. But not with promises to make their systems more “customer centric.” (We’ve been flagging that as a fail since 2008.) We need CRM that welcomes VRM. B2C that welcomes Me2B.

And money. Our startups and nonprofits have done an amazing job of keeping the VRM and Me2B embers burning. But they could do a lot more with some gas on those things.

❌